Streaming, Fast and Slow: Cognitive Load-Aware Streaming for Efficient LLM Serving
summary
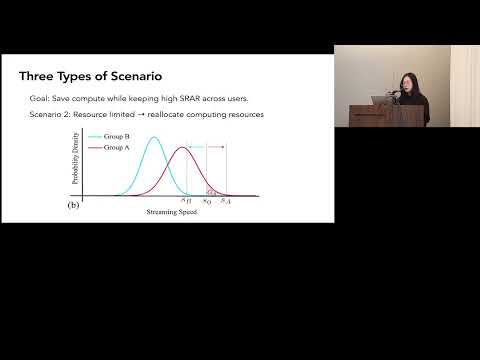
Proposes cognitive-load-aware streaming that paces token output by inferred difficulty using two predictors: Flesch–Kincaid and LLM self-prediction (it embeds a hidden numeric load token per chunk). Collects reading speeds from 200 Prolific participants over 10 passages, models speeds as log-normal, and simulates adaptive allocation across concurrent requests. Results show about 16% compute savings at 95% SRAR (≈14% at 90%); implementation is chunked streaming; limits include unmodeled GPU/network latency and non-text outputs like code.
AI-written summary · about
chapters (6)
- 0:00Introduction and motivation
- 1:40Problem and core idea
- 3:05Theoretical analysis
- 6:33Implementation and experiments
- 9:19Results and limitations
- 10:01Conclusion and Q&A
related talks
 26mEfficiently serving LLMs at scale.
 24mLLM Inference Optimization From Simple To Sophisticated
 30mAccelerated LLM Inference with Anyscale
 20mSGLang: An Efficient Open-Source Framework for Large-Scale LLM Serving
 43mLLMs in the Wild - Streaming, RAG, and Real Time GenAI at Scale
 16mServerlessLLM: Low-Latency Serverless Inference for Large Language Models
 14mScalable Solutions for Running Large Language Models
 18mServing Fast and Smart: Getting the Most Out of Ray Serve LLM on GKE