Enhancing XR Audio Realism via Multimodal Scene-Aware Acoustic Rendering
summary
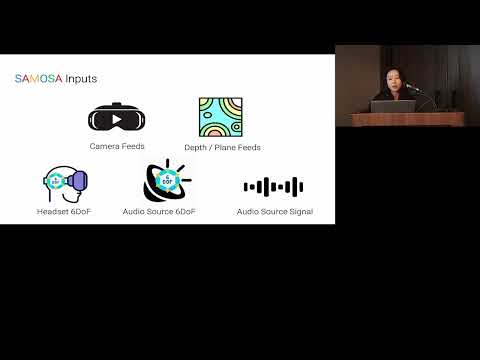
Samosa is an on-device hybrid pipeline that combines geometric ray-based shoebox estimation with learned acoustic priors to synthesize dynamic RIRs and convolve them with source audio in real time using roughly 3% of headset compute. It uses camera and depth feeds plus DeepLabV3+ for material masks refined via Segment Anything and a VLM, trains acoustic embeddings from ambisonic recordings across 25 rooms, and reports RT60/EDT parity with offline methods and a N=12 expert study showing better naturalness and externalization.
AI-written summary · about
chapters (7)
- 0:00Introduction to XR audio realism
- 2:54Challenge in XR audio rendering
- 3:55Simosa system overview
- 5:08Input and pipeline components
- 7:14RIR synthesis and applications
- 8:16Evaluation and future insights
- 10:05Q&A session
related talks
 10mTowards Context-aware Automatic Haptic Effect Generation for Home Theatre Environments
 20mSpatial Communications at Scale in Virtual Environments
 27mThe Making of an Ambient World: The Future of XR is Now
 29mIs XR the Next Big Thing? Immersion, Collaboration, and More!
 41mComputer Vision for Remote AR
 09mMulti-modal Multi-scale Attention Guidance in Cyber-Physical Environments
 21mComposing Spatial Music with Web Audio and WebVR
 22mIn two worlds at once: Social AR and VR