CAMP in the Odyssey: Provably Robust Reinforcement Learning with Certified...
summary
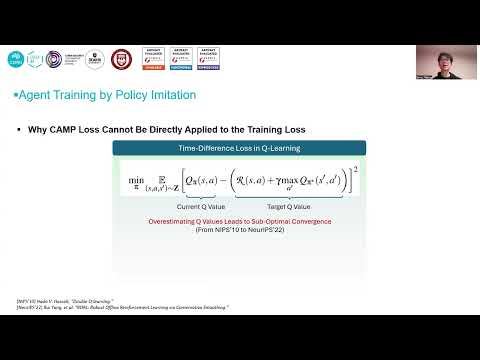
Introduces CAMP, a training paradigm that maximizes the provable certified radius by optimizing a surrogate loss derived from per-step local certified radii tied to the Q value gap and uses policy imitation to avoid Q overestimation instability. Reports experiments on six environments (3 classic control, 3 Atari), claims up to twice the certified expected return over Gaussian-augmented and NoisyNet baselines, and shows stronger empirical robustness under PGD and AutoAttack. Code at the linked GitHub.
AI-written summary · about
chapters (6)
- 0:00CAMP introduction
- 1:17DRL robustness background
- 3:27Research question and CAM loss
- 5:38Policy imitation for CAM loss
- 8:10CAMP experiments
- 11:28Summary of contributions
related talks
 28mDeep Reinforcement Learning: theory, intuition, code
 34mOffline Reinforcement Learning and Model-Based Optimization
 56mA Tutorial on Reinforcement Learning II
 42mReinforcement Learning using Generative Models for Continuous State and Action Space Systems
 52mReinforcement Learning for Autonomous Cyber Defense
 18mReward Augmentation in Reinforcement Learning for Testing Distributed Systems
 48mPractical Model-based Algorithms for Reinforcement Learning and Imitation Learning, with...
 15mMulti-Agent Reinforcement Learning In Stochastic Games: From Alphago To Robust Control