Machine Learning Attacks – A New Era of Security Epidemic

summary
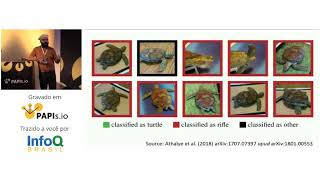
Claims that production models are breakable by tiny perturbations and by tampering with feedback, with concrete results: an image classifier flips from panda to gibbon using a 0.7x loss perturbation, and a fintech multifeature classifier drops from 99.9% accuracy and 100% recall to ~80%/80% after poisoning training data by over-weighting key names, exposing unencrypted card data. Defenses tested include mixed adversarial minibatches for retraining, blurring during training, threshold comparisons against a held ground-truth random testing set, and regular review of training inputs.
AI-written summary · about
chapters (7)
- 0:00Introduction to ML security risks
- 3:08Why ML models are vulnerable
- 6:29Types of adversarial attacks
- 9:18Real-world attack examples
- 13:13Poisoning attack demonstration
- 16:03Defending against adversarial attacks
- 19:41Summary and Q&A
related talks
 28mSecurity of Machine Learning
 36mAdversarial Machine Learning: How Secure Is ML?
 53mSecurity of Machine Learning Systems
 46mA Short Introduction to Hacking Artificial Intelligence
 44mComputers are Stupid: Protecting "AI" from Itself
 36mAdversarial Attacks on Deep Learning
 21mAdversarial Attacks
 02h 13mUnderstanding Security Threats Against Machine/Deep Learning Applications