Analyzing streaming data with Apache Druid

summary
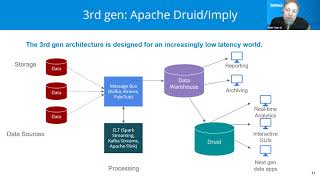
Apache Druid ingests Kafka/Kinesis/MSK streams natively with true stream ingestion and guarantees exactly‑once delivery, placing events into the database and S3 continuous storage so queries see late arrivals correctly. Typical query availability falls around 10–20 ms, with sub‑second analytic queries at high concurrency (hundreds per modest server) and production clusters reported up to 15,000 nodes / 400 PB. Used for operational visibility (Atlassian 3 billion events/day), observability (ThousandEyes), ad decisioning (Reddit) and IoT, plus a Polaris cloud service and hybrid managed options.
AI-written summary · about
chapters (8)
- 0:00Analyzing streaming data
- 2:16Real-world use cases
- 4:26Key Druid applications
- 5:58Streaming challenges
- 9:33Why choose Druid
- 12:23Druid history and use
- 14:07Introducing Imply
- 17:22Imply on AWS and resources
related talks
 46mScalable Realtime Analytics using Druid
 39mApache Druid 101
 28mBest of Stream + Batch: When Streaming Analytics Isn’t
 45mDruid: Powering Interactive Data Applications at Scale
 27mSucceeding with Apache Druid and Clickstream Data
 20mReal-time analytics with Flink and Druid #bbuzz
 41mBuilding an Open Source Streaming Analytics Stack with Kafka and Druid
 28mThe Heat is On: Architecting for Hot Analytics