Best of Stream + Batch: When Streaming Analytics Isn’t
summary
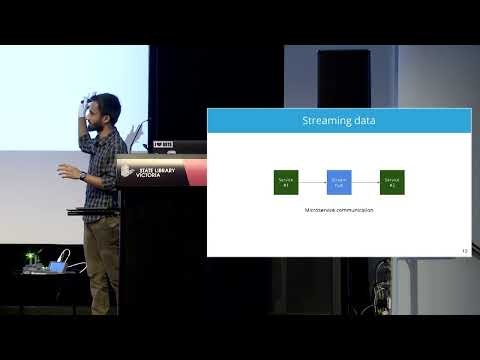
Demo claim: Apache Druid stores event streams and batch loads to deliver sub-second queries and serve dashboards without separate stream processors plus KV stores. It ingests continuously (up to million events per second), scales to hundreds of servers and thousands of concurrent users, and handles ~10,000 QPS with features like automatic compaction, bitmap and dictionary indexes, Apache DataSketches approximations, mmap-driven scanning and SQL/JDBC access. Deployments at Yahoo, Netflix and Airbnb report billions of events scanned in under a second, replacing custom stream+batch plumbing.
AI-written summary · about
chapters (13)
- 0:00Streaming analytics challenges
- 4:38Data warehouses to streaming
- 7:04Streaming data ingestion use cases
- 8:49Streaming systems limitations
- 12:21Streaming dashboards need more
- 15:06Druid for real-time analytics
- 17:14Druid key features
- 19:22Druid ingestion subsystem
- 21:51Druid query optimizations
- 23:14Druid success stories
- 24:59Druid sub-second queries
- 26:23Druid integration patterns
- 27:04Getting started with Druid
related talks
 20mAnalyzing streaming data with Apache Druid
 27mSucceeding with Apache Druid and Clickstream Data
 39mApache Druid 101
 10mData Rivers — The New Analytics Architecture
 21mPutting big data self-service analytics in the hands of business people
 27mTales at Scale: Analytics at 1000 QPS and Beyond
 22mBatching Was Yesterday: Real-Time Tracking & Analysis For 100+ Million Visitors
 32mSome Like It Hot