The Heat is On: Architecting for Hot Analytics
summary
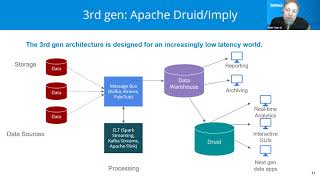
Apache Druid is presented as a high‑performance serving database that ingests from Kafka or batch, stores indexed partitions locally and pushes backups to S3/HDFS, and delivers 24–59× faster than Presto on the same data. Production clusters load 100 billion rows/day, trillions retained with sub‑second to few‑second query latency. Query engines fetch on demand and offer spot elasticity in seconds or minutes, while Druid trades elasticity for speed and a scaling rebalance ~1–2 hours when nodes change.
AI-written summary · about
chapters (6)
- 0:00Introduction
- 0:21Overview
- 7:07The Past
- 17:12Apache Druid
- 19:10How Druid Works
- 23:16Can We Have It All
related talks
 32mSome Like It Hot
 39mApache Druid 101
 38mApache Druid: Why Speed In Analytics Matters
 20mAnalyzing streaming data with Apache Druid
 27mTales at Scale: Analytics at 1000 QPS and Beyond
 28mBest of Stream + Batch: When Streaming Analytics Isn’t
 21mPutting big data self-service analytics in the hands of business people
 27mSucceeding with Apache Druid and Clickstream Data