Druid: Powering Interactive Data Applications at Scale

summary
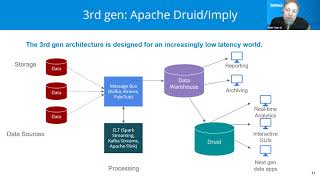
Druid is an Apache‑licensed column‑oriented distributed database that stores immutable time‑sharded segments per hour, uses dictionary encoding and bitmap indexes, and rolls up events to reduce storage often 40–100x. It supports streaming ingestion via in‑memory real‑time nodes that hand off to historicals, integrates with Kafka Hadoop Spark and Presto, runs production clusters at about 3 million events per second and >100 PB raw (≈500 TB segments), and returns queries around 500ms average latency.
AI-written summary · about
chapters (22)
- 0:00Intro
- 1:14History & Motivation
- 4:27Use Cases
- 10:14Business Intelligence Queries
- 12:22Solution Space
- 13:07Relational Database
- 14:50Key/Value Stores
- 19:10General Compute Engine
- 20:58Column stores
- 23:04Raw data
- 23:21Summarization
- 24:52Segmentation
- 26:19Columnar Storage
- 28:56Plugin Architecture
- 29:28Approximate Algorithms
- 31:16Architecture (Batch Ingestion)
- 32:14Real-time Nodes
- 33:08Architecture (Streaming Ingestion)
- 33:49Architecture (Lambda)
- 35:48End-to-end Data Stack
- 36:45Integration
- 37:19Takeaway
related talks
 46mScalable Realtime Analytics using Druid
 39mApache Druid 101
 27mCasting the Spell: Druid in Practice
 20mAnalyzing streaming data with Apache Druid
 40mBuild Real-time Analytic Applications: The Easy Way
 45mHow We Got Druid to Work at Odnoklassniki
 27mSucceeding with Apache Druid and Clickstream Data
 28mCasting the spell: Druid in practice