joins for a chat

summary
Covers concrete Kubernetes fixes: how readiness and liveness probes need per-dependency tuning so a slow Redis or legacy API won’t repeatedly fail pods, and why continuous monitoring and a fallback plan catch day‑2 regressions. Explains image hygiene—don’t rely on latest tag and pick the right imagePullPolicy to avoid unexpected pulls—and debugging with kubectl exec -it to inspect entrypoint and filesystem. Notes provider-specific StorageClass defaults and the practical trick of patching a CronJob schedule to “February 30” to stop misbehaving jobs.
AI-written summary · about
chapters (13)
- 0:00Introduction
- 0:38What is your talk about
- 1:42What is health checks
- 3:48fallback plan
- 4:39image replacement
- 6:10worker node
- 7:01image policy
- 8:12docker hub
- 8:59storage classes
- 10:13default
- 12:03calendar
- 13:05Difficulties in giving a talk
- 13:27Conclusion
related talks
 30mAfterlife tales: Troubleshooting containerized applications
 36mKubernetes Confessions: Real Mistakes We’ve All Made (and What They Teach Us)
 05mLightning Talk: 7 Tips for Tricks to Enjoy Your Kubernetes Journey
 42mMastering Kubernetes: Challenges, Strategies, and Best Practices
 59mKubernetes - going beyond the basics
 50mKubernetes - going beyond the basics
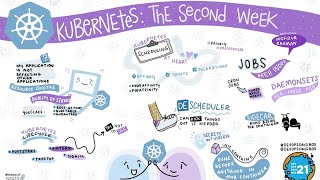 44mKubernetes: The Second Week
 34mReading 100+ Kubernetes Post-Mortems - lessons learned