Kubernetes Confessions: Real Mistakes We’ve All Made (and What They Teach Us)
summary
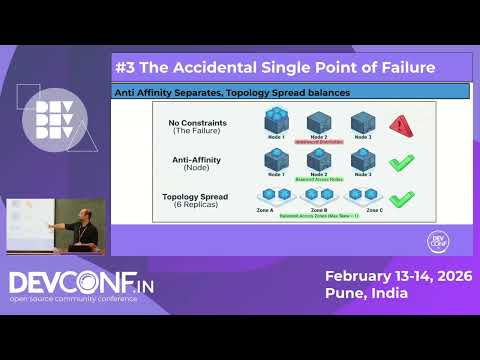
Seven reproducible failure modes with fixes: missing CPU/memory Vertical Pod Autoscaler recommendations and Prometheus history cause an analytic pod to grab 8 CPUs and 28 GB, trigger swap thrash and autoscaler churn; PDB set with minAvailable and replicas=1 blocks kubectl drain—use maxUnavailable/maxSurge or increase replicas; pod anti‑affinity/topologySpread prevents HA-bin‑packing; default allow network policies expose metadata; missing probes let pods show RUNNING but fail; privileged containers and unchecked Helm defaults lead to cluster compromise; huge images + imagePullPolicy:Always + 50 replicas stall deployments.
AI-written summary · about
chapters (10)
- 0:00Introduction
- 1:34Noisy neighbor meltdown
- 5:59PDB drain stuck
- 9:09Single point of failure
- 12:12Sidecar security risk
- 15:15Pods not running
- 18:30Container root access
- 23:17Default values disaster
- 27:17Registry pulling halt
- 31:56Summary
related talks
 20m10 Common Things People Do Wrong in K8s Environments
 34mReading 100+ Kubernetes Post-Mortems - lessons learned
 35mKubernetes, Lessons Learnt
 05mReading 100+ Kubernetes Post-Mortems
 30mWhat we learned from reading 100+ Kubernetes Post-Mortems
 33mWhat We Learned from Reading 100+ Kubernetes Post-Mortems
 35m10 Weird Ways to Blow Up Your Kubernetes
 37m10 Ways to Shoot Yourself in the Foot with Kubernetes, #9 Will Surprise You