Apples, Oranges, and ML Models: Model Validation vs Benchmarking
summary
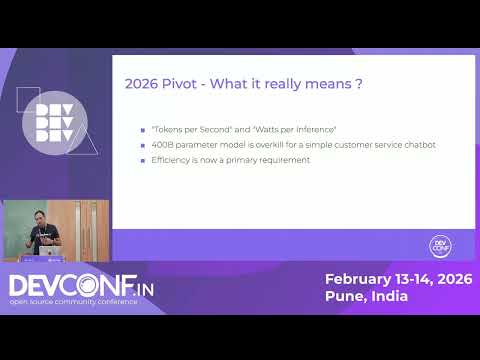
Red Hat is building a scalable system to evaluate LLMs, distinguishing benchmarking (relative leaderboards like MMLU) from validation (fit for a specific use case), arguing teams should pick by benchmarks then run a validation set unseen, stress tests and continuous monitoring. Notes surprising pivots: agentic workflows, preference for smaller efficient models, sovereign AI; concrete metrics that now matter are tokens per second and watts per inference, and 90% accuracy can still fail in production.
AI-written summary · about
chapters (13)
- 0:00Introduction
- 2:30Model validation matters
- 4:17From experiment to business AI
- 6:02Strategic AI adoption
- 8:06Trust gap and regulations
- 10:17Accuracy limitations
- 11:03Benchmarking vs validation
- 13:34How benchmarking works
- 15:01AI benchmarks and issues
- 15:44Validation as driver’s test
- 16:48Benchmarking vs relevance
- 17:31Deployment checklist
- 17:54Summary
related talks
 35mA simple way to validate and monitor the performance of your ML Applications.
 30mHow to Properly Test ML Models & Data
 14mImproving Large Language Model Performance
 54mKeynote: Can you trust your (large language) model?
 30mFrom Black Box to a Known Quantity: How to Build Predictable, Reliable ML-based
 32mStrategies for LLM Evals (GuideLLM, lm-eval-harness, OpenAI Evals Workshop)
 30mBuilding Teams and Culture that Support ML Innovation
 35mEnsuring Reliable Evaluation Systems for Your ML