Apache Hop
summary
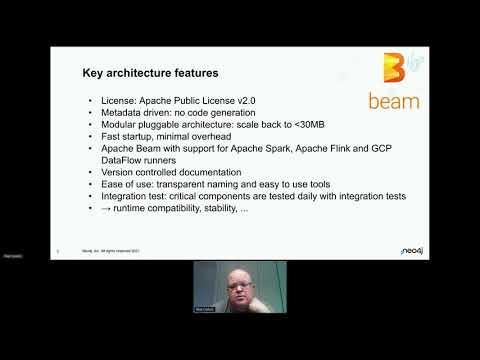
Apache Hop is a metadata-driven orchestration platform rewritten from a 20-year codebase into a modular, lightweight system that boots in JVM startup time and can be trimmed below 30 MB. Claims: 129+ bug fixes on the 0.99 release and voting on 1.0; engineering: automated license headers, removal of GPL-tainted code, and single-sourced web/gui. Integrations: runs on Spark/Flink/Dataflow via Apache Beam and exposes projects via VFS. Testing: hundreds of nightly integration pipelines prove backward compatibility.
AI-written summary · about
chapters (20)
- 0:00Intro
- 0:33Agenda
- 1:13What is Apache Hop
- 2:18How did Hop come about
- 3:40Where to find Hop
- 4:18Why Apache Hop
- 5:04Requirements
- 6:09Architecture
- 7:59New GUI
- 8:45GUI Configuration
- 12:15Data Orchestration
- 15:57Unit Tests
- 17:29Dataflow
- 19:27Documentation
- 20:31Incubator
- 22:42Copyright headers
- 25:10Existing code
- 31:22Integration tools
- 35:49Roadmap
- 38:14Questions
related talks
 21mApache Beam (incubating)
 39mHops in the Cloud
 45mMulti-tenant Flink-as-a-Service on YARN
 17mWhat's new with Hoppscotch?
 41mApache Beam: Unified Data Processing
 47mApache Beam - what do I gain?
 33mContainerizing & Orchestrating Hadoop Infrastructure at Scale
 18mAmerica First Credit Union optimizes their MLOps stack with Hopsworks