ZeRO-Offload: Democratizing Billion-Scale Model Training
summary
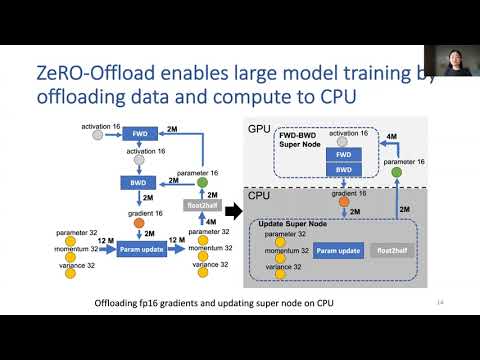
ZeRO-Offload offloads fp16 gradients and fp32 optimizer states and runs parameter updates on CPU while keeping forward/backward on GPU, enabling 30 billion parameters on a single NVIDIA V100 and up to 70 billion parameters across 16 GPUs with model parallelism. It reports ~40 TFLOPS/GPU for a 10B model, near-linear scaling to 128 GPUs, lower CPU–GPU communication than prior offload systems, an optimized multi-threaded CPU optimizer, and an open-source PyTorch implementation that needs no model refactoring.
AI-written summary · about
chapters (18)
- 0:00Intro
- 0:27The Size of Deep Learning Model is increasing Quickly
- 0:47Billon-Scale Model Training - Scale Out Large
- 3:32Mixed-precision training
- 5:10Limiting CPU Computation
- 5:47Minimizing Communication Volume
- 6:22ZeRO-Offload enables large model training , offloading data and compute to CPU
- 6:41Unique Optimal Offload Strategy
- 7:06ZERO-Offload Single GPU Schedule
- 8:01ZERO-Offload Multi-GPUs Schedule
- 8:44Optimized CPU Execution
- 10:38Evaluation
- 11:03Model Scale
- 11:28Training Throughput - Single GPU
- 11:59Training Throughput - Multiple GPUs
- 12:38Throughput Scalability
- 12:58One-step Delayed Parameter Update (DPU)
- 13:38Conclusions
related talks
 25mDistributed Training in PyTorch: Zero to Hero
 26mDeepSpeed: Efficient Training Scalability for Deep Learning
 13mFrom Silicon to Scale: Training at Scale
 24mEfficient Large-Scale Language Model Training on GPU Clusters Using Megatron-LM
 16mMegaScale: Scaling Large Language Model Training to More Than 10,000 GPUs
 38mMPI Meets Machine Learning: Unlocking PyTorch distributed for scaling AI workloads
 17mAccelerating Collective Communication in Data Parallel Training across Deep Learning...
 12mThe Ultra-Scale Talk: Scaling Training to Thousands of GPUs