Building Data Intensive Microservices with Apache Kafka

summary
Argues that Kafka replaces fragile DB-as-integration patterns with a partitioned, offset-addressable transaction log so multiple microservices and stores consume the same stream, enabling replay after failures (LinkedIn used it in 2010 to recover state), and supporting exactly-once semantics in recent versions. Describes Kafka Streams for in-process stream processing and KTables as per-key in-memory state for local joins, and Kafka Connect for source/sink connectors; shows this architecture scales and reduces outbound load on databases.
AI-written summary · about
chapters (19)
- 0:00Start
- 0:53Let's build a microservice
- 3:35Let's use the db for integration
- 5:29What if we could do it differently?
- 6:37Apache Kafka
- 8:31Once upon a time in LinkedIn
- 11:01Topics
- 11:41Producers
- 15:06Consumers example
- 18:26Stream Processing
- 19:38The KStream API
- 22:39The Stream-Table duality
- 23:57The KTable API
- 25:08Why are KTables important?
- 26:59KTable Summary
- 32:40Kafka Connect
- 34:25Connectors
- 36:19Connector Example
- 40:32The confluent platform
related talks
 50mBuilding Data Streaming Platform with Apache Kafka
 21mHow Apache Kafka® Generates Value In Retail With Confluent
 33mMicroservices, Events, and Breaking the Data Monolith with Kafka
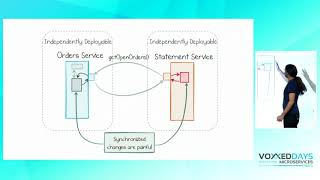 48mIntegrating microservices by accepting the data dichotomy
 33mKafka Microservices with Kafka plus Akka and Kafka Streams
 42mCreating event-driven microservices: the why, how and what
 17mOvercome By Events - Apache Kafka And Event-oriented Architecture
 55mThe hardest part of microservices: Your Data