Reliability and Resilience in the Cloud
summary
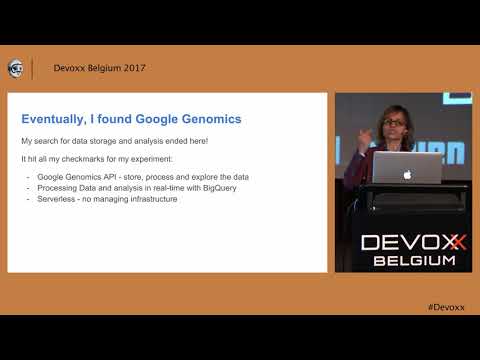
Build proves a cloud-native pipeline that stores and queries petabyte-scale genomic data using Google Genomics backed by BigQuery, with application services deployed on Pivotal Cloud Foundry and brokered via a service broker (Spring Boot) so apps bind without exposing IPs or keys. Interactive analytics return in seconds on terabyte-scale examples; the experiment handles roughly 52 petabytes for a city-sized population and completes end-to-end, showing the stack scales and the approach works.
AI-written summary · about
chapters (10)
- 0:00Introduction and context
- 1:34Defining cloud native goals
- 5:32Experimental data selection
- 9:11Data storage and processing
- 11:51Application infrastructure
- 14:34Service broker concept
- 17:34Service broker implementation
- 20:11Serverless portability
- 23:00Key takeaways and results
- 27:18Final Q&A and summary
related talks
 12mState of Cloud Foundry on Google Cloud Platform
 04mLightning Talk: Google Cloud Data Services and Cloud Foundry
 47mCloud Native and Sustainable, Reproducible Scientific Computing
 21mCloud Foundry on Google Cloud Platform
 07mCloud architecture for population-scale analyses of genomes and AI.
 33mManaging IoT Storage with Google's Cloud Platform
 37mCloud, security, and science converge in a data-driven world (PRT324)
 37mBuilding a Data Platform from scratch