A Practical Guide to Robust Multi modal Machine Learning in Education
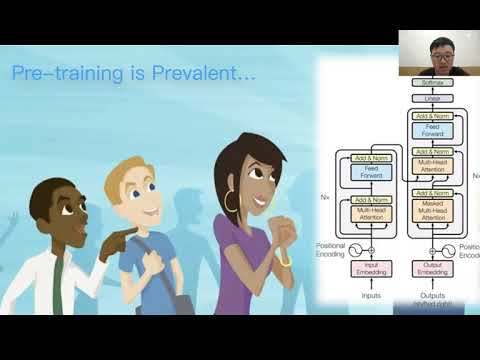
summary
Describes a multimodal pipeline that aligns word timestamps to audio, extracts word-level acoustic embeddings, and fuses them with text via temporal alignment and a sigmoid-weighted cross-modality excitation; yields higher emotion-recognition accuracy on standard speech benchmarks and open-sourced code. Introduces a pre‑training cross‑modal transformer (CTEL) with multi‑head cross‑attention and orthogonal regularization. For OCR/noise resilience, generates rule/attack/model-based corruptions, mines hard examples and adds a stability loss, achieving robustness up to ~10% OCR noise.
AI-written summary · about
chapters (6)
- 0:00Introduction to talk
- 2:58Multimodal learning for audio and language
- 8:15Pre-training cross-model transformer
- 12:30Robust language learning with noise
- 26:00Educational multimodal applications
- 35:40Conclusion and future work
related talks
 15mMulti-Modal AI Optimization: Combining Text, Vision, and Speech Efficiently
 13mInside Multimodal Models
 01h 23mMultimodal Deep Learning in the Real World
 28mLarge Multimodal Models: Understanding the State of the Art in Compute
 20mMultimodal language models
 12mIntroduction to TorchMultimodal
 59mTechnical Workshop: Sarcastically Speaking: Unlocking Multi-modal Sentiment Analysis With NLP and Facial Expressions
 19mLLM-Enhanced Multimodal AI: Revolutionizing Audio/Video Interaction