Accelerating Distributed Graph Learning by Using Collaborative In-Network...

summary
Offloads GNN multicast and many‑to‑one aggregation into the network using a P4 programmable switch and DPDK host stack, implements graph-aware multicast reordering (prioritizes high‑degree vertices to avoid queue stalls) and multi-level graph partitioning (split boundary vertices into memory‑sized blocks so in‑switch aggregators don’t overflow), and runs DCQCN‑style congestion control. Real testbed and NS3 results show up to 74% faster training, up to 81% less network traffic with 10–100 MB switch memory on datasets including Reddit and OGBN products.
AI-written summary · about
chapters (7)
- 0:00Switch GNN introduction
- 2:50Scaling GNN training challenges
- 3:55Programmable switches reduce bottlenecks
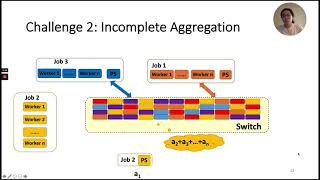
- 5:43Naive aggregation limitations
- 9:21Switch GNN design key ideas
- 13:19Implementation and results
- 15:31Summary
related talks
 11mScaling Distributed Machine Learning with In-Network Aggregation
 14mLeapGNN: Accelerating Distributed GNN Training Leveraging Feature-Centric Model Migration
 15mMGG: Accelerating Graph Neural Networks with Fine-Grained Intra-Kernel Communication...
 12mATP: In-network Aggregation for Multi-tenant Learning
 14mP3: Distributed Deep Graph Learning at Scale
 17mBGL: GPU-Efficient GNN Training by Optimizing Graph Data I/O and Preprocessing
 14mBrain-on-Switch: Towards Advanced Intelligent Network Data Plane via NN-Driven Traffic...
 19mNeuGraph: Parallel Deep Neural Network Computation on Large Graphs