Beyond Lists: High Performance Data Structures

summary
Claims concrete wins: replacing naive arrays/lists with an unrolled linked list boosts throughput from ~100 trades/sec to 10,000 trades per second while dropping CPU from near 100% to almost zero; switching to a cache-friendly column store (kdb style) cuts round trips from seconds to milliseconds; in-place array quicksort runs <100ms vs immutable list sorts >1s; B+ tree implementations scale to hundreds of millions with low cache miss cost. Uses F#/C#/C++ code, Visual Studio/YourKit profiling, GitHub samples and practical benchmarks.
AI-written summary · about
chapters (18)
- 0:00Intro
- 2:05Data driven applications
- 4:07Halfbaked databases
- 6:23Making things faster
- 6:54C vs F
- 9:09Prefixes
- 9:40Mutable Lists
- 10:24Beyond Addition
- 10:54Code Samples
- 14:23Laziness
- 15:51Streams
- 16:55Reactive Extensions
- 19:05Lookups
- 21:32Arrays
- 25:26Dictionary
- 35:23Un unrolled Linked List
- 38:28Btree
- 43:03Profiling
related talks
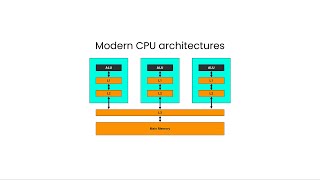 24mDesigning Fast and Efficient List-like Data Structures
 48mTricks from in-memory databases
 56mWhy Data Access Patterns Have Always Mattered
 35mFast on paper, slow in reality: what we got wrong about performance
 01h 13mC++ Memory Model Meets High-Update-Rate Data Structures
 45mMost of the Time It Works Every Time: The Mindset Behind Using Probabilistic Data Structures
 21mBuilding Distributed Platforms at Extreme Scale on Fast Changing Data
 48mA Helicopter Tour of Purely Functional Data Structures