SplinterDB: Closing the Bandwidth Gap for NVMe Key-Value Stores
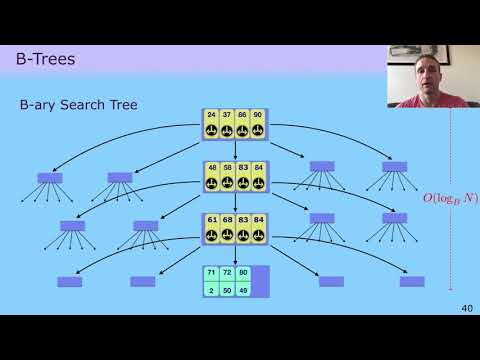
summary
SplinterDB implements a new data structure, the STBε-tree, plus a flush-and-compact execution model and a small-cache design, and it runs on an Intel Optane 905p with 32 cores and a cache ~5% of dataset. Measured against RocksDB, it delivers 6–10× insertion throughput, 2–2.6× point-query throughput, halves write amplification, and sustains 95% device bandwidth (versus ~30% for RocksDB). The system is built end-to-end and the benchmarks show the design works.
AI-written summary · about
chapters (8)
- 0:00Introduction
- 0:16Overview
- 5:36Performance
- 11:35Size 2Bepsilon tree
- 12:12Size 3Bepsilon tree
- 14:00Size 4Bepsilon tree
- 16:49Flush Compact
- 22:50Conclusion
related talks
 12mSpanDB: A Fast, Cost-Effective LSM-tree Based KV Store on Hybrid Storage
 19mSILK: Preventing Latency Spikes in Log-Structured Merge Key-Value Stores
 37mMoving on from RocksDB to something FASTER
 26mLeveraging Moore's Law to Optimize Database Performance
 15mImproving Performance of Flash Based Key-Value Stores Using Storage Class Memory...
 13mClosing the B+-tree vs. LSM-tree Write Amplification Gap on Modern Storage Hardware...
 23mRubbleDB: CPU-Efficient Replication with NVMe-oF
 24mPerformance tuning in BlueStore & RocksDB