Machine Learning: The Bare Math Behind Libraries

summary
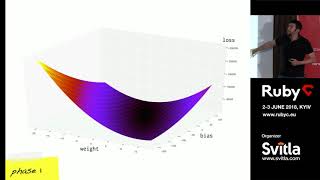
Linear regression with gradient descent in Octave examples fits costume price to comic appearances and yields a concrete example: $1,000 in costume predicts ~8,000 issues after 1,000 iterations. A shallow neural net (200 hidden neurons, sigmoid) learns a Batman-like logo perfectly on 600 training points but degrades on a 25,000-point grid — signs of overfitting. Unsupervised experiments use normalized six-attribute Marvel vectors and compare Hebbian learning, winner-takes-all and winner-takes-most (100 epochs); Hebbian blows up weights, winner-takes-most and SOM stabilize clusters.
AI-written summary · about
chapters (12)
- 0:00Intro
- 1:32Machine Learning
- 4:43Biological Neuron
- 5:48Activation function
- 7:02What defines a superhero?
- 12:19Gradient descent
- 20:41NN - backpropagation step
- 27:20Unsupervised learning
- 37:45Hebbian learning weaknesses
- 47:57Learning with concurency - weaknesses
- 50:21Common weaknesses of artificial neuron systems
- 51:26Bibliography
related talks
 44mMachine Learning: The Bare Math Behind Libraries
 33mMachine Learning explained to humans
 45mFrom Ancient Greeks to Modern Geeks - Basic Machine Learning Algorithms
 44mMachine Learning Exposed
 51mMachine Learning Explained to Humans
 51mMachine Learning Exposed Introduction to Machine Learning
 51mMachine Learning Exposed Deep and Reinforcement Learning
 45mApplied machine learning: a few lessons I learned the hard way