The Trial - GraphQL Streaming with Kafka
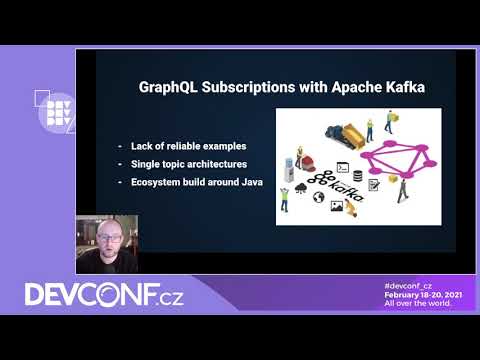
summary
Shows a concrete pipeline: dbzm connectors emit database change topics into Kafka, consumer processes those topics and feeds a GraphQL subscription engine over websockets, with partitions keyed by primary key to preserve order. Recommends an event marker consumption pattern where events carry only what changed and the server re-queries the DB to resolve the full GraphQL payload, enabling lightweight topics, batching, consumer groups and offset control. Notes limits (replica lag, no per-client time travel) and mentions example code in the aerogear org and follow-up blog posts, plus use of delta queries for initial sync.
AI-written summary · about
chapters (8)
- 0:00Data streaming basics
- 1:09GraphQL subscription mechanics
- 2:59Challenges and Kafka introduction
- 5:07Change data capture with Debezium
- 7:32Reference architecture
- 10:20Streaming architectural patterns
- 12:46Implementing the marker approach
- 15:33Open source tools and conclusion
related talks
 01h 07mKafka Streams and KSQLDB
 01h 00mIn Depth Kafka Streams
 53mApache Kafka and KSQL in Action : Lets Build a Streaming Data Pipeline!
 43mApache Kafka and KSQL in Action: Let’s Build a Streaming Data Pipeline!
 39mKafka as a Platform: The Ecosystem from the Ground Up
 41mKafka as a Platform: The Ecosystem from the Ground Up
 03h 00mStream Processing, Going Beyond Pub/Sub with Kafka Streams and...
 24mStreaming Events vs Live Queries, a deeper look at Subscription Patterns