CICD Pipeline and delivery of Apache Spark Applications on the cloud using AWS
summary
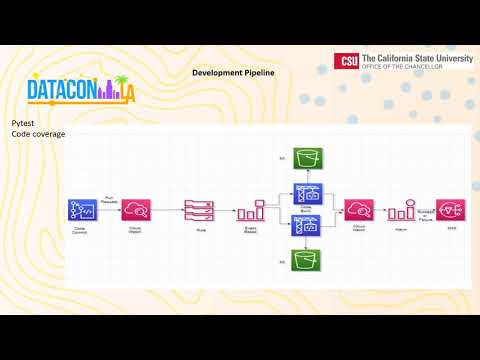
Claims a working CI/CD for Apache Spark on AWS that cuts manual steps by automating build, test, integration and multi-account deployment. Pipeline uses CodeCommit -> CloudWatch -> three CodeBuild jobs (pytest, coverage, EMR submit), spins EMR clusters via CloudFormation and CodePipeline, writes parquet to S3, and auto-terminates clusters. Production deploys cross-account with STS assume-role and KMS keys. Security includes MFA, IAM least privilege, Secrets Manager and GuardDuty. Remaining gaps: job orchestration in EMR and limited cross-account visibility; plan to evaluate Step Functions or Airflow.
AI-written summary · about
chapters (10)
- 0:00Introduction and context
- 1:40Project background
- 3:05CSU overview and goals
- 4:06DevOps and agile adoption
- 6:43AWS components for CI/CD
- 10:14CI/CD workflow processes
- 12:54Security measures
- 16:16Development pipeline details
- 20:21Production deployment
- 22:29Challenges and next steps
related talks
 38mAccelerating innovation through AWS Cloud technology
 26mIntelligent Deployment Pipelines
 23mCI/CD at Scale: Best Practices with AWS DevOps Services
 25mCI/CD in AWS Cloud
 55mEmpower innovation and agility with security in DevOps
 23mCI/CD at Scale: Best practices with AWS DevOps Services
 34mKick-Ass Tools and Processes for Scalable Data Science
 31mContinuous Software Delivery Using Spinnaker and Jenkins in Cloud