C++ Algorithmic Complexity, Data Locality, Parallelism, Compiler Optimizations, & Some Concurrency

summary
Concrete claims, measurements, and fixes: traversing a 4096×4096 double matrix rowwise takes row: 21 ms vs column: 912 ms, measured with valgrind; L1=32 KB L2=256 KB L3=8 MB and cache line 64 B explain it; D1 miss rates fall from 12.5% to 2.1% when access is cache-friendly. Blocking (32×32) or copying a submatrix removes conflict misses, false sharing creates ping‑pong between threads, and practical advice is: prefer contiguous containers (vector/flat_map), eliminate pointer/virtual chasing on hot paths, use PGO and benchmark.
AI-written summary · about
chapters (19)
- 0:00Intro
- 0:30Hardware
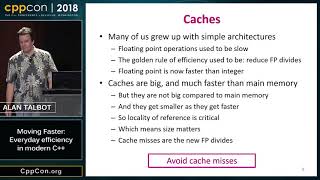
- 3:00Caches
- 3:53My Machine
- 4:50Cores
- 5:18Latency
- 6:13Cache Models
- 8:23Cache Lines
- 12:59Cache Misses
- 15:20Cache Miss Example
- 21:05False Sharing
- 24:50Cache Line Example
- 26:37Main Cache
- 27:18Memory
- 28:01Summary
- 28:54ObjectOriented Example
- 36:21Cash oblivious
- 37:36Guidelines for code
- 39:28Benchmarking
related talks
 28mCommunication Avoiding Algorithms for Linear Algebra and Beyond
 01h 00m“Want fast C++? Know your hardware!"
 01h 04mDesign for Performance
 58mC++ Performance and Optimisation
 01h 00mMoving Faster: Everyday efficiency in modern C++
 01h 02mSqueezing the Hardware to Make Performance Juice
 01h 00mCache Friendly C++
 01h 04mCompile-time sparse matrices