Advanced Document Parsing for AI Workflows

summary
Claim: a local pipeline parses PDFs, HTML and images into structured JSON/markdown/YAML and preserves tables, columns and bounding boxes so RAG answers improve. It uses an open source project called Dockling hybrid chunker (IBM Research, 40,000 stars), vision models for table/image parsing, OCR fallback, and runs on CPU or accelerator. Demo builds a local RAG with miniLM embeddings and Llama 3.2, shows better Q&A than recursive splitting, and flags PII with bounding boxes.
AI-written summary · about
chapters (17)
- 0:00Introduction
- 1:05Why document parsing matters for AI
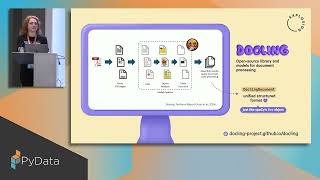
- 2:51Introducing Dockling
- 5:41Dockling’s PDF and document parsing
- 7:04Limitations of Beautiful Soup
- 9:11Dockling’s layout-aware parsing
- 10:36Parsing complex documents
- 11:39How Dockling uncovers structure
- 13:02Chunking strategies for RAG
- 15:27Dockling’s hybrid chunking
- 16:10Converting documents with Dockling
- 16:51Extracting images in documents
- 17:33Demo: chunking methods
- 18:55Building RAG with Dockling
- 19:59Hybrid vs recursive chunking
- 22:07Key takeaways and project resources
- 22:49Q&A
related talks
 01h 00mComplex Data Ingestion with Open Source AI
 29mConquering PDFs- document understanding beyond plain text
 22mContexts & Machines: How Document Parsing Shapes RAG results
 21mStructuring the Unstructured
 22mStructuring the Unstructured : Empowering the AI Workflows
 18mLLMs and GenAI: A Guide to Building Your Own RAG Model for Document Interaction
 39mEnterprise-ready document processing for AI
 39mAgentic RAG Platform for AI-Assisted Workflows