Building Production-Ready Data Pipelines for AI/ML with Lambda Architecture
summary
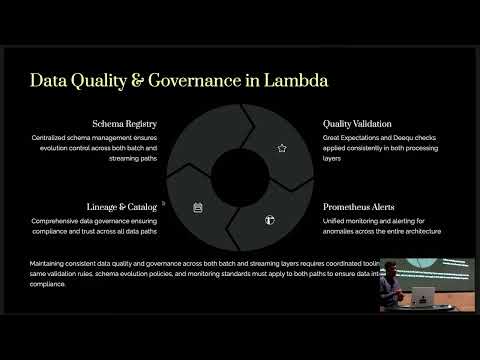
Eighty percent of AI projects fail for data quality, scalability, or stale features, so the concrete claim is that a Lambda architecture pairing batch layer (hourly/daily complete, heavy validation with Great Expectations, schema registry, Parquet/Avro) and speed layer (small-window streaming to Redis/Cassandra, feature store freshness) plus unified serving reconciles fresh inference with eventual accuracy, uses Prometheus alerts and canary deployments, costs more but measurably reduces production drift and speeds deployments when implemented with infrastructure as code.
AI-written summary · about
chapters (20)
- 0:00AI data pipeline challenges
- 1:43AI projects fail in production
- 3:27Data pipeline workflow
- 5:12Training versus inference needs
- 5:52Lambda architecture layers
- 7:19Batch layer for accuracy
- 9:24Speed layer for real-time
- 10:25Serving layer schemas
- 11:28Reconciling batch and speed
- 13:14Data quality and governance
- 14:41Windowing and triggers tuning
- 15:44Resource management
- 16:24Serialization trade-offs
- 17:06Observability and debugging
- 18:30Canary deployments
- 18:52CI/CD for data platforms
- 19:33Infrastructure as code
- 19:54Data governance
- 20:35Business impact of Lambda
- 21:39Production-ready checklist
related talks
 41mInfrastructure for ML Applications
 33mBuilding Resilient (ML) Pipelines for MLOps
 53mNoLambda: A new architecture combining streaming, ad hoc, machine...
 19mDemystifying Modern Data Pipeline Architecture
 26mEngineering Excellence: Platforms and Architectures for Real-Time AI Analytics
 16mOperationalizing AI in Finance: Real-Time Analytics
 28mDataEngBytes 2023 - PER-T1-05 - Ellie Gholami
 34mBuilding scalable end-to-end deep learning pipelines in the cloud