Conquering PDFs- document understanding beyond plain text
summary
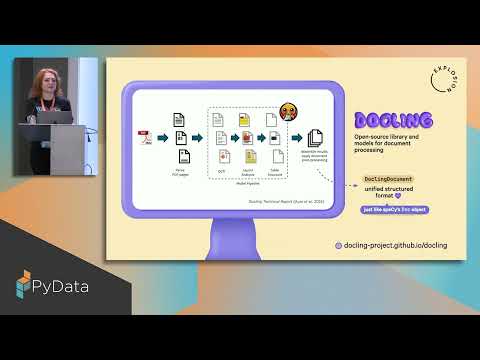
Claims that PDFs are a bad source of truth and that extracting a unified structured format first makes document pipelines manageable. Uses Dockling plus a spaCy layout plugin to return a doc object with layout spans, bounding boxes and tables converted to pandas DataFrame. Shows annotation via Prodigy recipes with a focus mode, trains NER with a 30% quick-eval split, and reports compact deployable models (around 6 MB models) that run locally on a laptop.
AI-written summary · about
chapters (14)
- 0:00Introduction
- 2:10PDFs as messy data
- 4:17PDFs as flawed truth
- 7:05Spacey Layout and Dockling
- 9:11PDFs to structured objects
- 11:19PDF layout + NLP pipelines
- 13:23Handling PDF tables
- 16:33Tables to natural language
- 17:14Modular workflows
- 20:06Custom NLP for PDFs
- 22:12Prodigy annotation
- 24:21Training NLP on PDFs
- 26:06Scaling PDF processing
- 26:27Key takeaways and future of PDF processing
related talks
 31mConquering PDFs: document understanding beyond plain text
 26mAdvanced Document Parsing for AI Workflows
 01h 00mComplex Data Ingestion with Open Source AI
 01h 25mLearn to Unlock Document Intelligence with Open-Source AI
 01h 07mMeet Docling: The “Pandas” for Document AI
 31mDocling: Get Your Documents Ready for Gen AI
 01h 19mLearn to Unlock Document Intelligence with Open-Source AI
 24mTeaching PyTorch To Read Your Worst PDFs With Docling