Gathering Insights from Audio Data

summary
Describes converting audio (8 kHz phone to 44.1 kHz CD) and formats (WAV, MP3, FLAC), extracts MFCCs with librosa, and trains an LSTM via Keras/TensorFlow on a Kaggle Freesound set (9k clips, 41 classes, 3,700 verified examples). Uses Sox, Audacity, pandas, scikit learn and Jupyter for preprocessing, saves numpy arrays, calls AWS Transcribe via boto3 for speech to text, applies NLTK VADER and spaCy plus pyLDAvis for topic modeling, reports ~0.61 F1, initial live test 3/5 correct, works but needs more tuning and GPU time.
AI-written summary · about
chapters (24)
- 0:00Introduction
- 1:14Why are we here
- 2:23How we hear
- 3:30How computers hear
- 4:07What is amplitude
- 4:51Sampling
- 6:28Format
- 7:50Channels
- 9:57Audacity
- 11:12Raw Audio
- 11:55Spectrogram
- 13:07Chroma Graham
- 13:51MMSCC
- 15:15Dubrow
- 18:05Free Sound Audio Tape
- 18:47Data Loading
- 22:37Model
- 23:55Training
- 25:42Testing
- 28:43Transcription
- 29:37Nuance
- 30:21Transcription Demo
- 32:27Keyword Search
- 37:41Text Analysis
related talks
 28mHow to use Deep Learning to process audio data and classify sounds.
 31mClassifying Audio into Types using Python
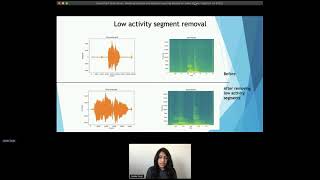 40mBuilding Features and Machine Learning Models for Audio Signals
 25mLooking at Sound
 22mImplementation and analysis of deep learning models for speech classification
 31m“Sorry, Could you repeat that again?” - Speech Recognition with Python
 34mText-to-Speech Data Preparation and Fine-tuning Workshop
 11mClassifying Spoken Location Names