High-performance dataframe-agnostic GLMs with glum
summary
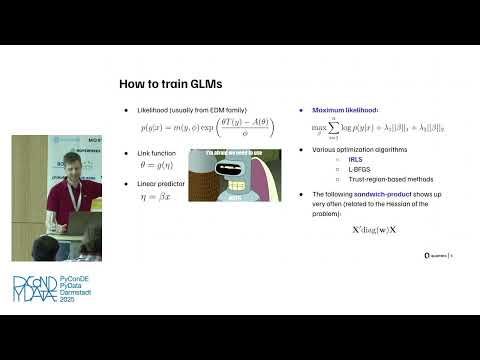
glum is a Python-first GLM implementation with a C++ TabMat backend and Cython hot paths that claims up to ~1,000x speedups on categorical sandwich-product work (example: 55 ms → 74 ns) by treating dense, sparse and categorical parts separately. it started as a scikit-learn PR, now exposes a data frame-agnostic from_df API via Narwhals, supports formulaic interfaces, optimizes the sandwich product and plans Arrow integration to avoid converting to numpy/scipy arrays.
AI-written summary · about
chapters (9)
- 0:00Introduction to GLMs
- 1:24Estimating GLMs efficiently
- 7:16Overview of Glam and Tabmat
- 11:18Handling mixed sparsity data
- 14:48Making libraries data-agnostic
- 16:48Implementation challenges
- 21:54Future developments
- 24:28Wrap-up and call to action
- 26:09Q&A session
related talks
 39mAccelerated Data Science Libraries
 31mcuDF: RAPIDS GPU-Accelerated Dataframe Library
 32mpyGAM: balancing interpretability and predictive power using...
 01h 12mGPU-Accelerated Data Analytics in Python
 19mOptimizations and abstractions for sparse machine learning
 30mIs the great dataframe showdown finally over? Enter: polars
 39mPushing Cython to its Limits in Scikit-learn
 02h 55mGPU Accelerated Python w: CUDA