Data Efficient Methods for Reinforcement Learning
summary
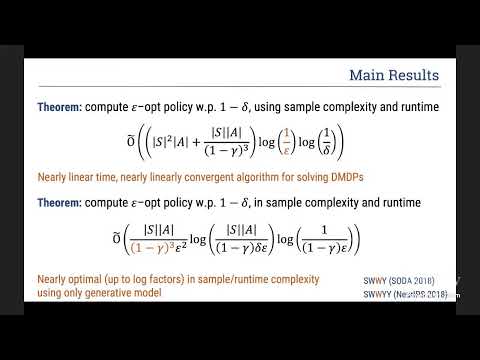
Claims provable speedups for SGD with experience replay on an autoregressive Markov chain showing loss decays exponentially with an improved dependence of T over the square root of the mixing time versus sequential SGD’s dependence over the mixing time, a diagnosis that Fitted Q‑Evaluation can diverge under common MLP architectures and fixes that stabilize it (ResNet, distributional FQE, shared representations, hypermodels) without losing accuracy, and two generative‑model algorithms that compute ε‑optimal policies with near‑linear runtime and logarithmic-in-1/ε sample complexity and a second near‑optimal cubic dependence on 1/(1−γ).
AI-written summary · about
chapters (10)
- 0:00Introduction
- 0:31Challenges
- 0:50Problem Setting
- 1:59Experience Replay
- 3:09Results
- 3:51Distribution Shift
- 5:12Algorithms
- 5:43Better architectures
- 6:48General data efficient algorithms
- 8:04Conclusion
related talks
 01h 05mFoundations of RL
 42mReinforcement Learning using Generative Models for Continuous State and Action Space Systems
 56mA Tutorial on Reinforcement Learning II
 28mOptimizing Long-Tail and MoE Challenges in Reinforcement Learning with SGLang
 01h 01mRobustness, Stochastics, Uncertainty 2
 01h 17mOnline Reinforcement Learning and Regret
 33mTradeoffs in Large Scale Learning: Statistical Accuracy vs. Numerical Precision
 55mOptimality and Approximation with Policy Gradient Methods in Markov Decision Processes