Robustness, Stochastics, Uncertainty 2
summary
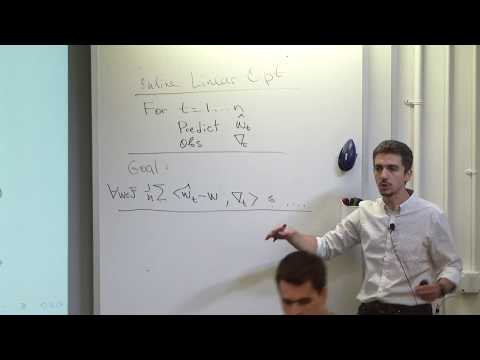
Shows that projected SGD and online linear optimization give a deterministic 1/√N regret for bounded gradients and that an adaptive stepsize (Adagrad-style) yields an upper bound matching the empirical Rademacher complexity for L2 geometry. Uses two-line projection proofs, dynamic-programming min–max rollbacks and softmax relaxations to recover exponential weights and √(log D / N) expert bounds. Points out a remaining gap: existence of an optimal Burkholder function is known for spectral norm but an efficient algorithm to evaluate it for matrix completion is still open.
AI-written summary · about
chapters (8)
- 0:00Introduction
- 11:17The Grand Goal
- 27:05Onlinesupervised learning
- 28:47Dynamic programming
- 46:00Results
- 47:26MinMax
- 53:20Randomization
- 55:13Online Linear Optimization
related talks
 58mFirst-Order Stochastic Optimization
 01h 18mOptimization I
 01h 07mOptimization Crash Course (continued)
 01h 05mOptimization for Machine Learning I
 33mTradeoffs in Large Scale Learning: Statistical Accuracy vs. Numerical Precision
 46mSmooth Nonconvex Min-Max Optimization
 42mWhat (Doesn't) Make Learning Algorithms Generalize?
 01h 04mOptimization for Machine Learning II