Completing the machine learning loop
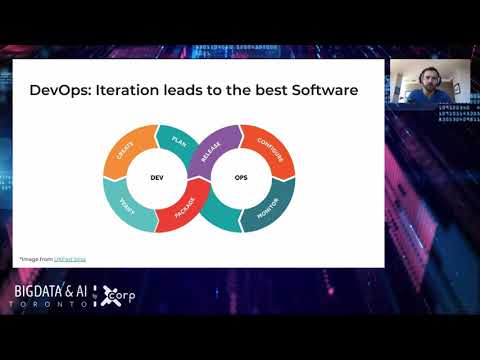
summary
Argues that reliable ML requires treating data like code and shows a concrete stack: git-like data repositories plus data-driven pipelines on Kubernetes that auto-run on data changes, version model artifacts, and produce full lineage so one can trace which data delta produced which model. Cites real failures — speech recognition edge cases, stickers fooling autopilot, GPT-3 bias — to justify heavy data testing and monitoring. Mentions the AI Infrastructure Alliance with ~60 members coordinating integrations rather than reinventing tooling.
AI-written summary · about
chapters (9)
- 0:00Introduction to ML loop
- 1:45What is machine learning
- 4:10Data bugs in ML
- 8:22DevOps for ML
- 12:55MLOps explained
- 15:24Current MLops challenges
- 19:18Pachyderm’s approach
- 23:51Future of ML stacks
- 25:15Summary and conclusion
related talks
 41mCan Data & ML really learn from software engineering?
 54mArtificial Intelligence seen from the software development lifecycle perspective
 33mAI with a DevOps mindset - experimentation, sharing ..
 27mContinous integration of ML products and UX design
 28mUnravelling Hidden Technical Debt in ML: A Pythonic Approach to Robust Systems
 21mHow The Application Of Machine Learning Is Changing The Way Companies Use Data
 26mThe Hidden Foundation: How Effective Data Management Determines AI System Success
 42mCI/CD for Machine Learning