Sparsity and Privacy in Distributed Matrix Multiplication
summary
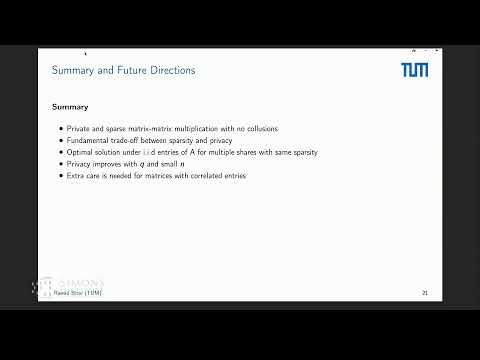
Claims that perfect information-theoretic privacy forces dense shares for sparse A,B, and that relaxing privacy lets shares keep zeros while leaking a tunable amount of information. Uses one-time pad and Shamir secret sharing mapped to polynomial evaluations, builds randomized R drawn conditionally on A with three parameters p1,p2,p3, and frames privacy vs sparsity as a convex optimization over p1,p2,p3 minimizing mutual information. Numerical results show leakage grows with desired sparsity and with number of shares; schemes are implementable and effective under the IID-entry model.
AI-written summary · about
chapters (6)
related talks
 33mPrivacy of Decentralized Machine Learning
 38mDemystifying Privacy Preserving Computing
 01h 31mIntroduction to Secure Multi-Party Computation
 35mPairwise Network Differential Privacy
 25mThe Whole is Greater than the Sum of its Parts: Linear Garbling and Applications
 28mPrivacy versus Robustness in Federated Learning: Limits and Algorithms
 30mDistributed Statistical Estimation of Matrix Products with Applications
 27mOn Distributed Differential Privacy and Counting Distinct Elements