Democratizing data with an internal data pipeline platform
summary
Describes building an internal data pipeline platform at Indix to catalog and process varied datasets (HTML, Thrift, Avro, CSV, Google Sheets) using Spark. It covers dataset discovery with schemas, configurable pipelines via a wizard or JSON, predefined transformations (filter, project, sample, SQL), autoscaled dedicated Spark clusters, S3/SFTP/Sheets connectors, notebook client access, and operational scale (300+ pipelines, 100+ datasets).
AI-written summary · about
chapters (5)
- 0:00Start
- 1:12Six Business Critical Indexes
- 2:31Data Pipeline alndix
- 4:34Scale of Data a Indix
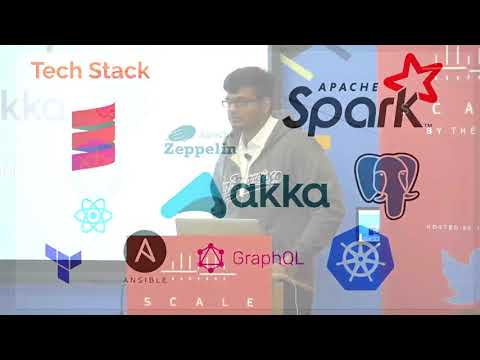
- 12:34Tech Stack
related talks
 36mApplying Functional Programming Principles to Large Scale Data Processing
 17mDemocratising data analytics
 05mInterview
 01h 35mDeep Dive into the Big Data Landscape
 27mData Analytics Democratization: How ING Data Analytics Platform Bootstraps New...
 04minterview
 31mOne Data Pipeline to Rule Them All
 42mBuilding Robust Streaming Data Pipelines with Apache Spark