The Data That Shapes Foundational LLMs
summary
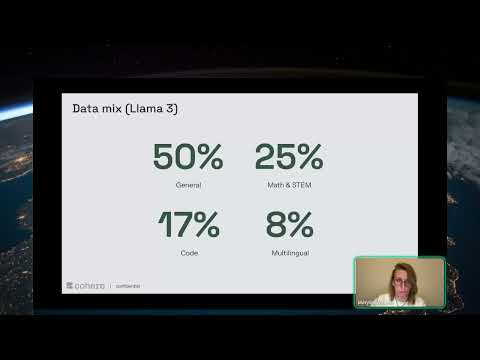
Explains concrete pipelines: HTML parsing, deduplication and ngram coverage filtering, and modelbased filters such as FastText to surface higherquality web docs; cites Llama 3 data mix 50/25/17/8 as an example of explicit source proportions. Describes pretraining (causal LM on curated mix) and posttraining: supervised fine-tuning with chat pairs, preference data for reward signals, synthetic augmentation plus human-in-the-loop verification; concludes syntheticonly data reinforces biases so human annotation and modelinloop prioritization remain necessary.
AI-written summary · about
chapters (19)
- 0:00Welcome
- 1:05Building foundational LLMs
- 2:31LLM training data misconceptions
- 3:15Pre-training data collection
- 5:49Filtering and deduplication
- 7:14Pre-training data mix
- 8:38Causal language modeling
- 10:24Limitations of pre-training
- 11:08Post-training for instruction
- 12:53Human annotation in fine-tuning
- 13:57Synthetic data challenges
- 15:25Good response training
- 16:49Prioritizing human annotation
- 19:58Human-in-the-loop importance
- 20:40Summary of LLM training data
- 21:07Q&A on LLM datasets
- 22:38Future of humans in training
- 24:49Enterprise post-training
- 25:57Safety in data handling
related talks
 01h 30mPreparing Data for LLM pretraining using open source Data Prep Kit
 43mImportance of data in the time of LLMs
 29mLocal LLM fine-tuning: a practical example
 46mUnder the Hood of LLMs — all those questions you never dared ask about them
 49mBen Hall & Barbara Fusinska
 01h 30mUsing LLMs to improve your Search Engine
 40mInstructLab: Applying Open Source Methods to Building and Trai...
 30mLearning to wield large language models