A Deep Dive into Python-Powered Precision and Scalability
summary
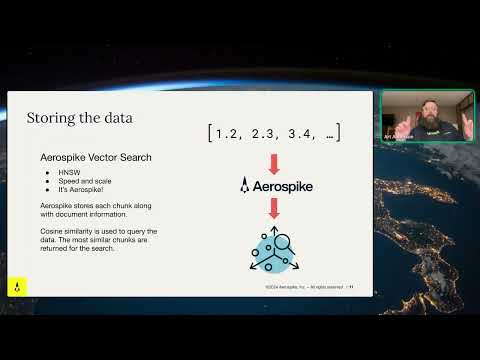
Builds a production site search that combines Gemini embeddings for 768‑dim vectors with an inverted index stored in Aerospike, using Scrapy, LlamaIndex, SpaCy, FastAPI and Uvicorn. Dataset is small (~6,000 chunks) yet achieves subsecond vector lookups via Aerospike’s distributed HNSW and caches query embeddings. Tried semantic reranking (Gemini = fast but poor quality; Go‑here model = accurate but slow) and ends up using reciprocal rank fusion for fast, reliable fusion of keyword and vector ranks.
AI-written summary · about
chapters (15)
- 0:00Welcome
- 1:29Better search for Aeros Spike
- 3:38Architecture and data pipeline
- 6:28Preparing data
- 8:58Generating embeddings with Gemini
- 10:47Storing vectors in Aerospike
- 12:30Vector search on queries
- 14:15Building keyword index
- 17:47Ranking with BM25
- 19:33Combining search results
- 21:39Optimizing with reciprocal rank fusion
- 22:43Serving API with FastAPI
- 23:46Frontend integration
- 24:54Future plans and open source
- 25:58Q&A
related talks
 57mUnlocking the Power of Hybrid Search: A Deep Dive into Python-Powered Precision
 27mUnified AI & Relational Power: Scalable Distributed Vector Search with
 41mPractical Vector Search Configuration, Tuning, RAG, and the Road Ahead
 27mMachine Learning for Advanced AI Search
 35mVector Databases: Using Vector Search with Graph and Key-Value Queries
 01h 23mVector Databases Demystified: Discover how they work
 57mEnter The Brave New World of GenAI with Vector Search
 36mUnleashing the Power of Vector Databases for AI-Driven Applications