Simplifying Training Deep & Serving Learning Models...using Tensorflow
summary
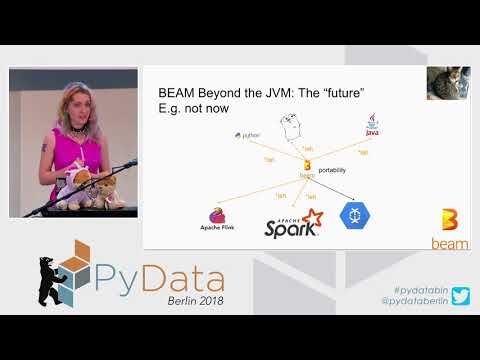
Hands-on pipeline work: building feature prep that computes constants with TF Transform, packaging Python into Docker via Beam’s portability layer and running TensorFlow on Flink (demo runs the Chicago taxi example doing string→int bucketing and z‑score scaling), then emitting a proper TensorFlow model for TF Serving. Demos are flaky (one in three chance of trouble), not production ready, and the vendor’s 242 times faster claim is misleading (realistic wins more like ~50%).
AI-written summary · about
chapters (20)
- 0:00Introduction
- 1:53Inclusivity in ML development
- 3:15Non-JVM support in Apache Beam
- 5:06Deep learning needs feature preprocessing
- 7:33TF Transform for feature prep
- 9:23TF Transform with TensorFlow
- 10:48Portability with Docker in Beam
- 12:35Python dependency challenges
- 14:02Chicago taxi data demo
- 17:41Python 2.7 challenges
- 19:47Demo to serving models
- 20:30Serving models with TF Serving
- 21:37Python integration in big data
- 24:28Dependency management in Beam
- 25:12TensorFlow on Spark with Arrow
- 27:42Arrow performance benefits
- 29:07Spark code with Pandas UDFs
- 31:19Java and TensorFlow mismatch
- 32:22Resources for Beam and Spark
- 32:47Q&A
related talks
 42mDeep learning beyond the learning
 01h 18mPutting Tensorflow Models into Production
 22mThe Containerization of Machine Learning: TensorFlow: Kubernetes, and Kubeflow
 57mMachine Learning Data Pipelines
 46mAccelerating Machine Learning DevOps with Kubeflow
 01h 18mPutting Tensor Flow Models Into Production
 43mDeep learning beyond the learning
 33mDeploying and Scaling Spark ML and Tensorflow AI Models