Modern ETL-ing with Python and Airflow (and Spark)

summary
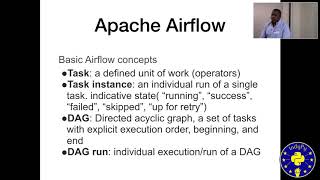
Claims that Python plus Apache Airflow and Apache Spark replace GUI ETL tools for production pipelines and shows it working at HelloFresh: Airflow runs scheduled and backfilled DAGs, supports dynamic DAG and task creation, and coordinates Spark jobs submitted via spark-submit (bash) or the SparkSubmitOperator against a Hadoop cluster. Practical notes: use two DAGs for historical vs incremental runs, avoid piping data between tasks (use XCom sparingly), watch scheduler metadata, and expect log tradeoffs between client and cluster modes.
AI-written summary · about
chapters (17)
- 0:00Start
- 0:36What To Expect
- 4:19Why Python
- 6:18Centralized Scheduling
- 6:44Alerting and Monitoring
- 8:32Dynamically Create Pipelines and Tasks
- 8:57Basic Air Flow Architecture
- 9:10Scheduler
- 11:39Depends on Past Properties
- 12:40Dag Runs Are Triggered When the Period Ends
- 13:12Incremental Loads and Transformations
- 16:23Command Line
- 16:57Docker
- 17:25Deployment
- 19:45The Spark Rest Api
- 20:57Summary
- 25:10Things That I Missed in the Past
related talks
 34mData Ingestion in Python using Apache Airflow
 36mElegant data pipelining with Apache Airflow
 18mETL at Scale: Optimizing PySpark + Airflow Workflows
 32mBuilding Analytics Workflow using Airflow and Spark
 39mHow Python Drives Modern Data Engineering
 32mOrchestrating Your Data Pipelines with Apache Airflow
 01h 25mApache Airflow in the Cloud: Programmatically orchestrating workloads w/ Py
 38mUse Apache-Airflow to Build Data Workflows