Data Ingestion in Python using Apache Airflow

summary
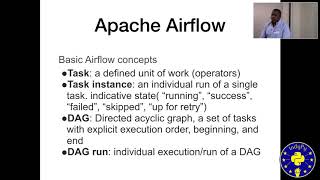
Apache Airflow orchestrates ETL pipelines by encoding DAGs in Python, storing task state in a metadata DB, and dispatching work via an executor like Celery to worker nodes; it runs Spark through a Spark operator, triggers on arrival with sensors and hooks, and supports backfill and cloud plugins (AWS/GCP). Operators are unit-testable and DAGs belong in CI and version control, with recommended idempotent tasks, immutable staging and persisted intermediate results. Integration testing is weak and the UI lacks auto-refresh and built-in RBAC.
AI-written summary · about
chapters (11)
- 0:00Introduction
- 4:20Concepts of Airflow
- 5:20Why Airflow
- 13:35Features
- 15:27UI Demo
- 17:02Best Practices
- 18:47Continuous Integration
- 19:44Data Pipeline
- 23:24Final Data Set
- 26:00Resources
- 26:35Machine Learning
related talks
 27mModern ETL-ing with Python and Airflow (and Spark)
 01h 59mIntroduction to orchestration ETL processes with Apache Airflow
 22mOrchestrate your data pipelines using Apache Airflow
 38mUse Apache-Airflow to Build Data Workflows
 01h 25mApache Airflow in the Cloud: Programmatically orchestrating workloads w/ Py
 01h 18mIntroduction to orchestration ETL processes with Apache Airflow
 35mBecome a Conductor with Apache Airflow
 45mDefining data pipelines