Implementing Reinforcement Learning for Marketing Channel Optimization with Python

summary
Implements a production-oriented pipeline: a negative binomial emulator (Bayesian/Stan-style) models impressions and clicks to simulate the environment, a policy network and value network output continuous action parameters sampled for budget allocation, and Proximal Policy Optimization with advantage estimates and clipping trains the agent. Uses Python tooling (Stan for the probabilistic emulator and Pyro to inject probabilistic layers), converges after thousands of iterations with reward saturation (~8800) and yields policy performance within a few percent of human decisions while adapting to daily incoming data.
AI-written summary · about
chapters (12)
- 0:00Introduction
- 1:51Marketing channel problem
- 4:22Optimization vs reinforcement learning
- 7:33Why use reinforcement learning
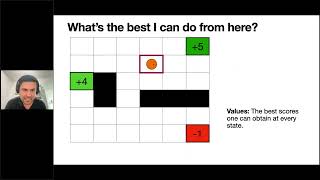
- 10:03Reinforcement learning basics
- 13:40Proximal Policy Optimization
- 17:01Environment modeling
- 20:40Combining components
- 26:03Implementation details
- 27:37Training results
- 28:21Future improvements
- 30:08Conclusion and Q&A
related talks
 29mReinforcement Learning Without a PhD: A Python Developer’s Journey
 01h 26mProbabilistic Programming and Bayesian Computing with PyMC
 41mPyMC-Marketing: Customer and Marketing Analytics the Easy Way
 25mML model from an idea to production with the help...
 42mMulti-channel optimal path sequencing through Bayesian DL
 29mReinforcement Learning with Human Feedback
 53mOff-policy Policy Optimization
 42mReinforcement Learning using Generative Models for Continuous State and Action Space Systems