Defining data pipelines

summary
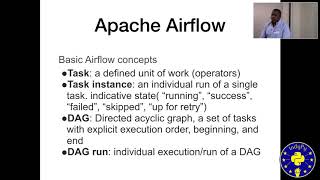
Idealista runs Apache Airflow daily to author pipelines as code using Airflow DAGs as Python code, with Bash and Python operators, built-in sensors, and integrations to AWS Glue/Athena and Slack; metadata lives in a SQL DB, logs can go to S3, and XCom passes small values between tasks. The scheduler remains a single point of failure at scale (Airbnb reports ~8,000 DAGs), backfill/time travel lets teams repair weeks of runs, and idempotent tasks plus retries and SLA alerts are recommended.
AI-written summary · about
chapters (11)
- 0:00Start
- 13:05Gantt Visualization
- 15:39Transfer Operators
- 19:32Dependency Graph
- 20:48Time Traveling
- 22:31Core Components
- 29:10Best Practices
- 36:57Deploying Airflow
- 38:43Scalability
- 39:24Scheduler
- 40:24Kubernetes
related talks
 22mOrchestrate your data pipelines using Apache Airflow
 34mData Ingestion in Python using Apache Airflow
 44mCreating Python Data Pipelines in the Cloud
 38mUse Apache-Airflow to Build Data Workflows
 29mDagster: a Framework for Data Processing Applications
 27mModern ETL-ing with Python and Airflow (and Spark)
 35mMaximizing Airflow: Advanced Techniques for Data Pipeline Orchestration
 01h 59mIntroduction to orchestration ETL processes with Apache Airflow