Building Analytics Workflow using Airflow and Spark

summary
Built global retail logistics analytics using Airflow + Spark and Hive, running nightly batch jobs that ingest RFID shipment and store scans into Postgres and S3 then transform with Spark into Hive/BigQuery. Shows concrete DAG code: Airflow DAG templating with runtime parameters, uses Celery executor for scale, Postgres metadata, Jenkins/GitHub deploys, and monitoring via Cloud Composer integration with Stackdriver/CloudWatch. Compares running and maintaining an on‑prem Airflow cluster versus using Cloud Composer and gives failure and HA behavior.
AI-written summary · about
chapters (16)
- 0:00Start
- 1:58Session overview
- 2:53Data pipeline
- 4:48Example: logistics operation monitoring
- 6:58Our requirements for ETL worflow
- 9:16Another workflow engine: Apache Nifi
- 10:02Airflow overview
- 11:11Example: Copy a file from s3 bucket to another
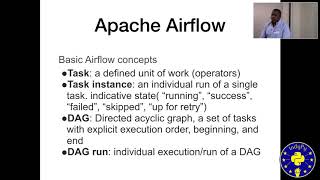
- 16:34Concept: Directed acyclic graph, operator, task, etc
- 17:16template
- 18:31HA Airflow cluster
- 23:32Create a cluster using CLI
- 24:14Deploy your source code to the cluster
- 24:59monitoring cluster using Stackdriver
- 25:21Demo: GCP Cloud Composer
- 28:03Summary
related talks
 01h 59mIntroduction to orchestration ETL processes with Apache Airflow
 38mLessons Learned from the Migration to Apache Airflow
 27mModern ETL-ing with Python and Airflow (and Spark)
 16mBridging Data Science and Data Infrastructure with Apache Airflow
 01h 25mApache Airflow in the Cloud: Programmatically orchestrating workloads w/ Py
 38mUse Apache-Airflow to Build Data Workflows
 36mGetting Started with Apache Airflow - Building Your First Workflow
 42mHow I learned to time travel, or, data pipelining and scheduling with Airflow