Modeling and Analyzing Evaluation Cost of CUDA Kernels
summary
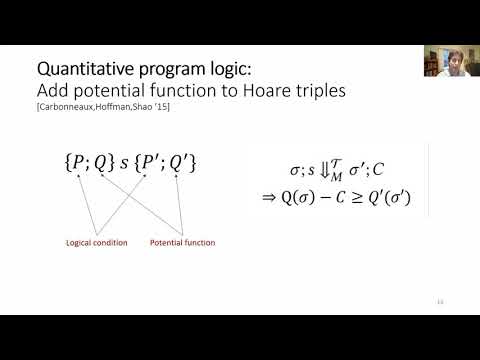
Paper presents a quantitative program logic and cost semantics for CUDA that are formalized in Coq formalization and implemented as the prototype tool vercuta built on top of absinthe. An LP-solver based inference engine synthesizes symbolic potential functions and infers bounds; analysis runs under a second on most kernels and predicts global-memory sector and warp-divergence costs with typical overestimates around 20–30%. A simulator and GPU profiler validate the model; worst-case bank-conflict cases are conservatively predicted and flag real performance bugs.
AI-written summary · about
chapters (11)
- 0:00Start
- 2:00Performance Drawbacks
- 2:42Shared Memory
- 4:20Cost Semantics
- 4:50Resource Metric
- 5:24Rules for if Statements
- 6:28Program Logic
- 8:31Potential Functions
- 23:52Histogram Benchmark
- 24:55Instruction Level Parallelism
- 25:14Conclusion
related talks
 18mCompiling Strassen-like Matrix Multiplication Algorithms to Fast CUDA Kernels
 16mPricing Python Parallelism: A Dynamic Language Cost Model for Heterogeneous Platforms
 27mShattering the AI Memory Wall
 15mUSHER: Holistic Interference Avoidance for Resource Optimized ML Inference
 31mBuilding Inference Workflows with Tile Languages
 29mBeyond CUDA: GPU Accelerated Computing on Cross-Vendor Graphics Cards with Vulk...
 01h 26mGPU Algorithm Authoring with CUDA Tile
 15mKareus: Joint Reduction of Dynamic and Static Energy in Large Model Training