MLSec Going Deeper
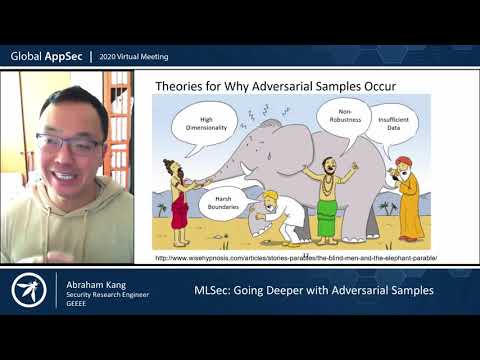
summary
Claims that adversarial samples hit nearly every model not just deep nets and demonstrates concrete attacks on k‑NN, Naive Bayes, linear classifiers, decision trees, random forests, SVMs and neural nets, showing model cloning and transferability and the math (gradients for nets, feature splits for trees). Shows practical tooling and notebooks including IBM Adversarial Robustness Toolkit and CleverHans, and evaluates defenses like adversarial training and removing non‑robust features, noting accuracy tradeoffs and when attacks succeed.
AI-written summary · about
chapters (12)
- 0:00Intro
- 0:43Adversarial Samples
- 8:29What Can You Attack
- 12:01Goal Intuition
- 13:20Attacking Procedure
- 19:33Naive Bayesian
- 22:19Linear Classification
- 26:31Decision Trees
- 29:49Random Forest
- 32:11Adversarial Attacks
- 33:46adversarial training
- 35:25adversarial robustness toolkit
related talks
 53mSecurity of Machine Learning Systems
 38mUsing adversarial samples to robustify your Neural Network Models
 02h 13mUnderstanding Security Threats Against Machine/Deep Learning Applications
 39mSecure Machine Learning: Overcoming Algorithmic Bias, Adversarial ML in the Wild West of AI
 36mAdversarial Machine Learning: How Secure Is ML?
 21mTricking Neural Networks : Explore Adversarial Attacks
 52mSleeping With One AI Open: An Introduction to Attacks Against...
 44mAdversarial attacks on deep learning models