Adversarial attacks on deep learning models

summary
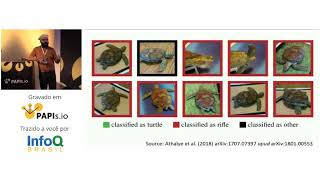
Covers adversarial perturbations that cause deep learning models (e.g., object-recognition CNNs) to misclassify by adding small structured noise, including the transferability of attacks between different network architectures or training sets. Describes methods for crafting adversarial images and surveys the most effective defenses developed to date for protecting models used in tasks like object recognition and semantic segmentation.
AI-written summary · about
chapters (19)
- 0:00Intro
- 0:49What are adversarial images ?
- 3:48Can't Deploy models
- 4:31Transferability
- 5:41Universal perturbations
- 6:48Fooling rates for UAP
- 8:36Linear model case
- 11:03Gradient wrt image
- 13:13Nonlinear models
- 13:56Simple gradient ascent on loss
- 14:35Other ways to generate
- 16:06Why do they exist?
- 19:22How to overcome them
- 20:25Empirical Methods
- 26:17Adversarial Training - drawbacks
- 31:31Layer-wise Contractive penalty
- 33:16Efficient Augmentation
- 35:01Robust perturbations
- 36:46Conclusion
related talks
 36mAdversarial Attacks on Deep Learning
 21mAdversarial Attacks
 02h 13mUnderstanding Security Threats Against Machine/Deep Learning Applications
 44mNeural Network Security: Live Demonstration of an Adversarial Attack
 36mAdversarial Machine Learning: How Secure Is ML?
 25mTricking Neural Networks : Explore Adversarial Attacks
 38mUsing adversarial samples to robustify your Neural Network Models
 21mTricking Neural Networks : Explore Adversarial Attacks