SRE implementation in a cool company
summary
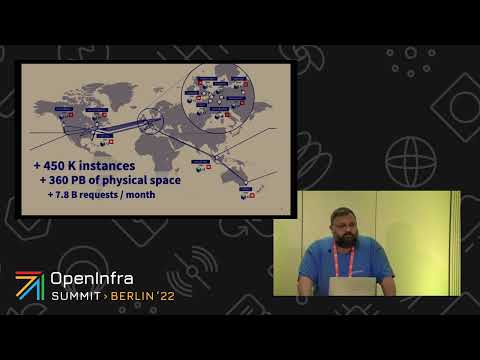
OVHcloud runs a fully integrated, water‑cooled infrastructure with 450k instances, 360 PB of storage and 40 regions, and adopts an SLO‑driven SRE model backed by a massive observability project that collects billions of SLIs. Automation detects failing hosts and evacuates VMs automatically; one person handles alerts one person on call 24/7 because most failures resolve without manual intervention. Stack work includes OpenStack on Kubernetes, Octavia with Barbican for TLS, Ironic for bare metal, and storage tech from OpenIO and extend.
AI-written summary · about
chapters (9)
- 0:00Introduction and speakers
- 1:25Company origins and cloud model
- 3:31Infrastructure and data center design
- 5:57Transition to SRE implementation
- 8:08Team structure and global collaboration
- 10:35Automation and hardware failure management
- 12:01New features and open source projects
- 14:06Conclusion and hiring call
- 14:49Q&A session
related talks
 35mSRE -- culture and strategy @ TrustingSocial
 41mBuilding an SRE Capability Inside a Large Organization
 15mSREs at Telecom and Media Industry: Bridging between Legacy and Cloud Native App
 43mSRE From Inception to Global Scale
 25mSRE in the Third Age
 30mDifferences in SRE Implementations across Companies
 27mSRE Drives Maturity Models
 30mThe Path to SRE