The data dichotomy: Rethinking data and services with streams

summary
Argues that service architectures must accept a data dichotomy and use a shared immutable log to both notify and replicate state, showing how Kafka plus connectors and CDC ingests legacy tables, compacted topics hold current keys, and KStreams (or stream processors) materialize tables, join streams with windows for use cases like fraud detection and order/payment emailing, use schema registry and the single-writer principle for compatibility, and rely on transactions and state stores to scale to millions of events per second.
AI-written summary · about
chapters (18)
- 0:00Start
- 0:17Ben Stopford
- 16:48Event-Driven Model
- 20:32What a Streaming Platform Is
- 21:16Kafka
- 23:58The Streaming Engine
- 24:10K Streams
- 25:50Stream Processing Engines
- 28:10What Is a Table
- 31:07Take Responsibility for the Past
- 34:31Use of Schemas
- 35:26Schema Registry
- 35:37Applying the Single Writer Principle
- 36:30Causal Consistency Model
- 39:23Query a Log
- 42:50Using the Log as a Database
- 53:45Data Dichotomy
- 54:16Event-Driven Services
related talks
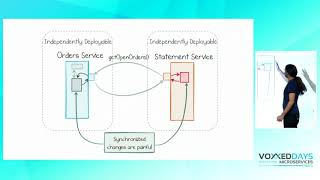 48mIntegrating microservices by accepting the data dichotomy
 59mBuilding Data Intensive Microservices with Apache Kafka
 47mStream All the Things!
 30mEvent Streaming and the Future of Applications
 27mKeynote II: Kafka and the Rise of Event-Driven Microservices
 30mChange Data Streaming Patterns in Distributed Systems
 55mThe hardest part of microservices: Your Data
 37mBeyond Microservices: Streams, State & Scalability