Software Heritage
summary
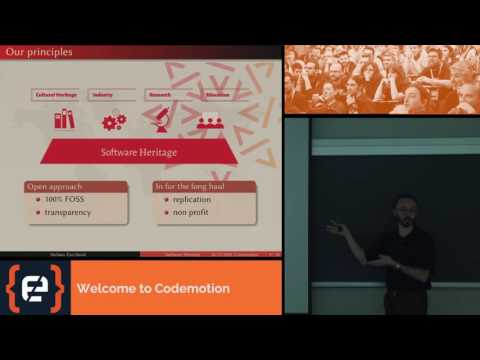
Project aims to collect, preserve, and share all publicly available source code and already archives 3 billion unique files, ~650 million commits across ~25 million projects. It crawls VCS and release tarballs, stores canonical objects in a Merkle-DAG-style object store with content deduplication, computes SHA-1/SHA-256 checksums, and records provenance. Prototype works: a full GitHub mirror plus Debian history and archived Google Code/Gitorious copies, ~150–200 TB compressed blobs and a ~5 TB metadata DB, with Internet Archive and cloud mirrors planned.
AI-written summary · about
chapters (11)
- 0:00Introduction and speaker
- 2:35Source code as knowledge
- 8:54Risks to software commons
- 9:16Introducing Software Heritage
- 11:43Project principles and transparency
- 13:06Archive contents and preservation
- 19:24Technical architecture overview
- 25:26Current archive status and numbers
- 28:17Features and future plans
- 30:24Project funding and partners
- 32:33Q&A and community involvement
related talks
 44mSoftware Heritage: DevOps challenges to preserve our software commons
 53mIntroduction to Software Heritage, the Alexandria library for code
 28mCodeCommons_ Towards transparent, richer and sustainable datasets for code generation model training
 42mFederal Source Code Study: An Analysis of Publishing the People's Code
 14mGitHub's Data Story: Open Source at the Home for Open Source
 57mOpen Source at commercial organisations
 41mSecuring the World’s Open Source Software, Together
 27mIs InnerSource Commons good for open source?