System Level Design: Interconnect and 3D Stacking
summary
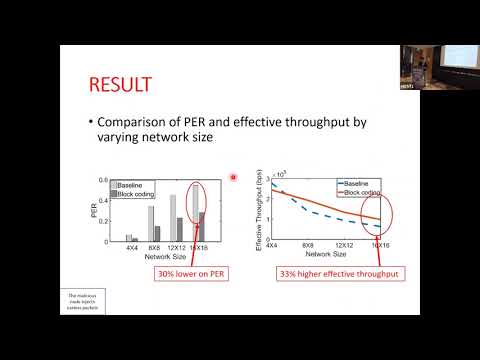
GCIM moves GCN aggregation into the logic die of a 3D‑stacked memory, adds lightweight bank‑level compute and a community‑aware partitioner, and reports about 20% latency reduction and a 27% increase in bank‑group hit rate. DirectGNN pairs structural pruning with crossbar‑aware mapping to cut peripheral crossbar count by >90%, reduce communication latency ~41%, and claim up to 2.7× runtime speedup. ML‑guided inlining (MLGoPerf) retargets rewards to performance and shows a 1.8% SPEC geometric mean speedup over -O3 (code size +17%).
AI-written summary · about