Why software developers should build a resilience culture based on chaos engineering
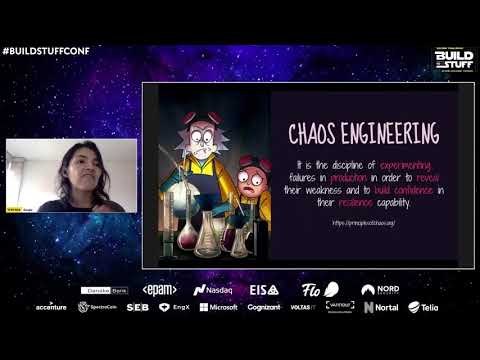
summary
Argues that developers must adopt chaos engineering as a daily discipline and gives concrete how‑tos: form a hypothesize steady state, inject faults (Chaos Monkey, FIT, Gremlin or scripts), run experiments that vary real‑world events, measure outcomes, then automate experiments in pipelines and record postmortems. Explains chaos game days with three roles (master of disaster, responders, postmortem), traces Netflix→FIT→Gremlin history, cites books (Site Reliability Engineering, Building Secure and Reliable Systems) and notes a global Slack community of >5,000 practitioners.
AI-written summary · about
chapters (10)
- 0:00Start
- 3:29Why Our Software Requires Resilience
- 9:41Working Memory
- 12:07Chaos Engineering
- 15:04Publication of a Book
- 16:27Psychological Life Safety
- 17:32Resilience Engineering
- 20:14Human Factors
- 29:35Building Secure and Reliable System
- 32:36Psychological Safety
related talks
 48mChaos Engineering: The Path to Reliability
 29mThe Psychology of Chaos Engineering
 26mBreaking Systems for Resilience
 18mChaos Engineering: Break It On Purpose
 21mThe Psychology of Chaos Engineering
 27mChaos Engineering: The Path to Reliability
 43mBetter Software Development Systems through Stress
 36mChaos Engineering