No Buffer, No Bottleneck: Efficient Zero-Copy KV Cache Offloading for Long-Context LLMs
Talkat 20th USENIX Symposium on Operating Systems Design and Implementation (OSDI '26) · 2026-07-13..07-15·
summary
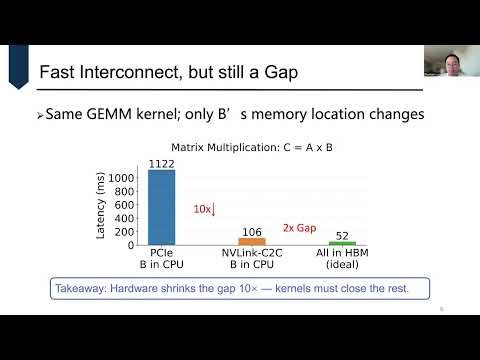
DirectKV implements a true zero-copy KV cache by letting CUDA kernels directly access CPU-resident KV blocks over NVLink-C2C on GH200/GB200, eliminating the GPU staging buffer and fusing projection with attention into one kernel. It uses warp-level pipelining and CPU-memory-aware tiling to hide fetch latency, reducing CPU–GPU transfer volume by up to 50% and cutting GPU HBM usage by 43%, yielding up to 1.2× end-to-end speedups (up to 2.4× under load) on long-context inference.
AI-written summary · about
chapters (12)
- 0:00Efficient KV cache offloading
- 1:26Long-context KV cache challenges
- 2:58PCIe-based KV offloading limits
- 4:05Grace Hopper interconnect
- 5:32Kernels for asymmetric memory
- 6:38Tiling for CPU-resident data
- 8:06Pipelining to hide latency
- 8:51Kernel fusion for transfers
- 9:59DirectKV architecture
- 13:12Evaluation and results
- 14:38Optimization impact
- 15:20Summary and future
related talks
 15mKV Cache: Accelerating AI Inference on Intel CPU
 33mScaling KV Caches for LLMs: How LMCache + NIXL Handle Network and Storage...
 11mLightning Talk: Inside VLLM's KV Offloading Connector: Async Memory Transfers for...
 44mVLLM K/V Caching With Ceph
 10mLightning Talk: KV-Cache Centric Inference: Building a State-Aware...
 19mBeyond the Node: Scaling Inference with Cluster-Wide KVCache...
 34mVLLM KV Cache Management: From Cache Reuse To Agent Scenario Optimization
 15mBidaw: Enhancing Key-Value Caching for Interactive LLM Serving via Bidirectional...